
Problem-driven lead
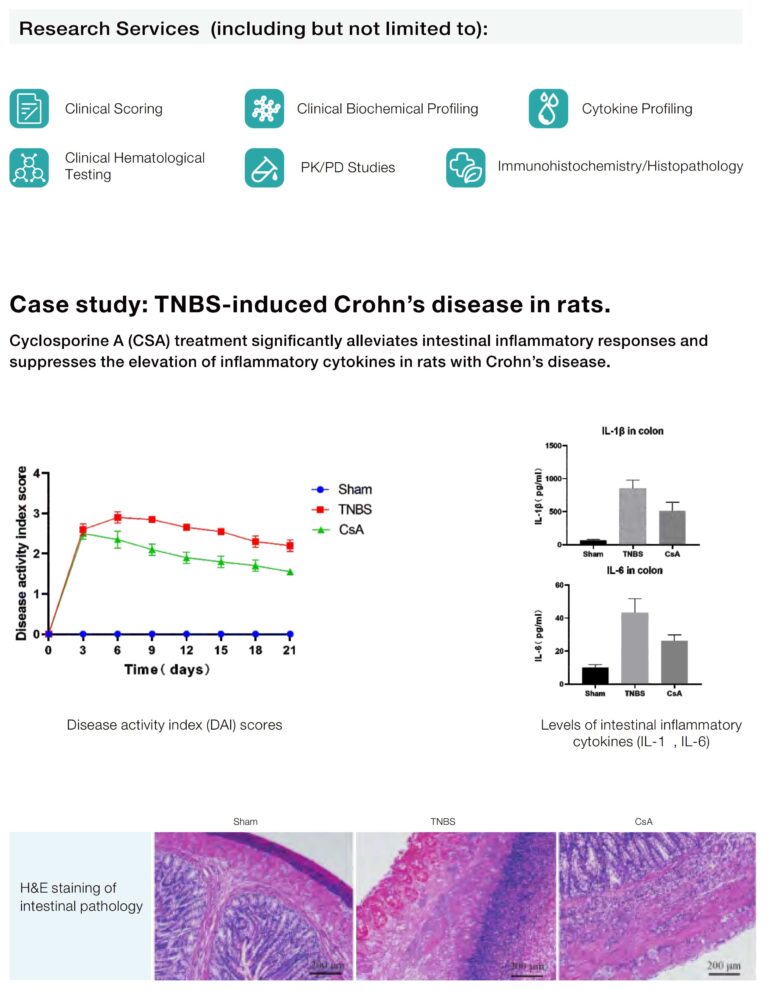
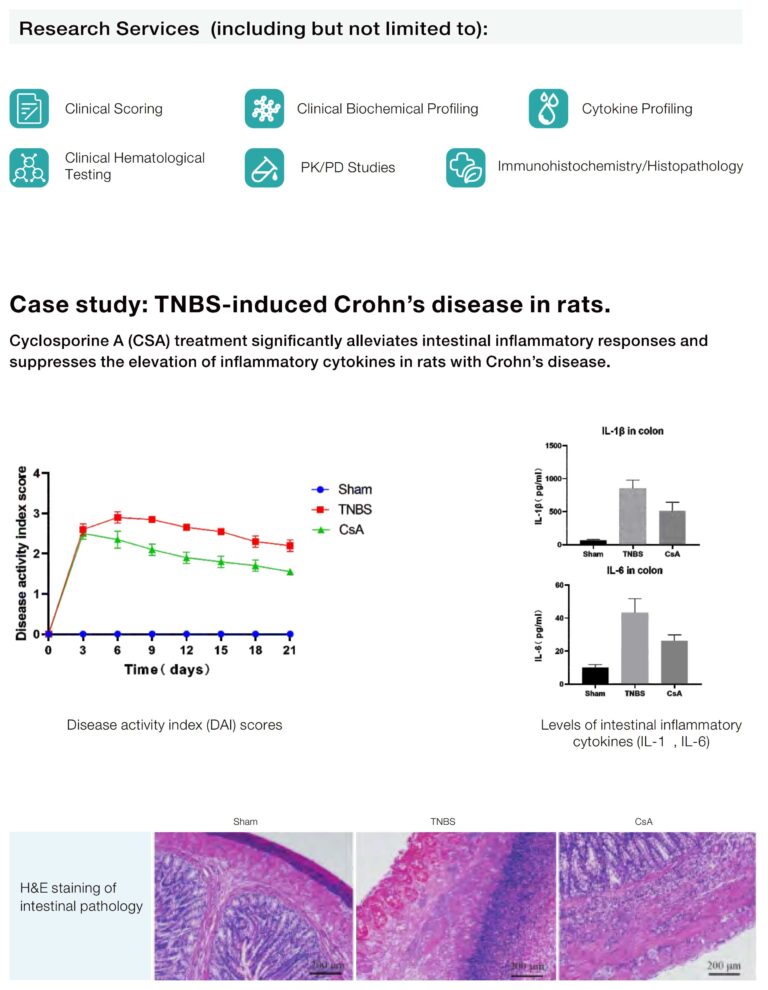
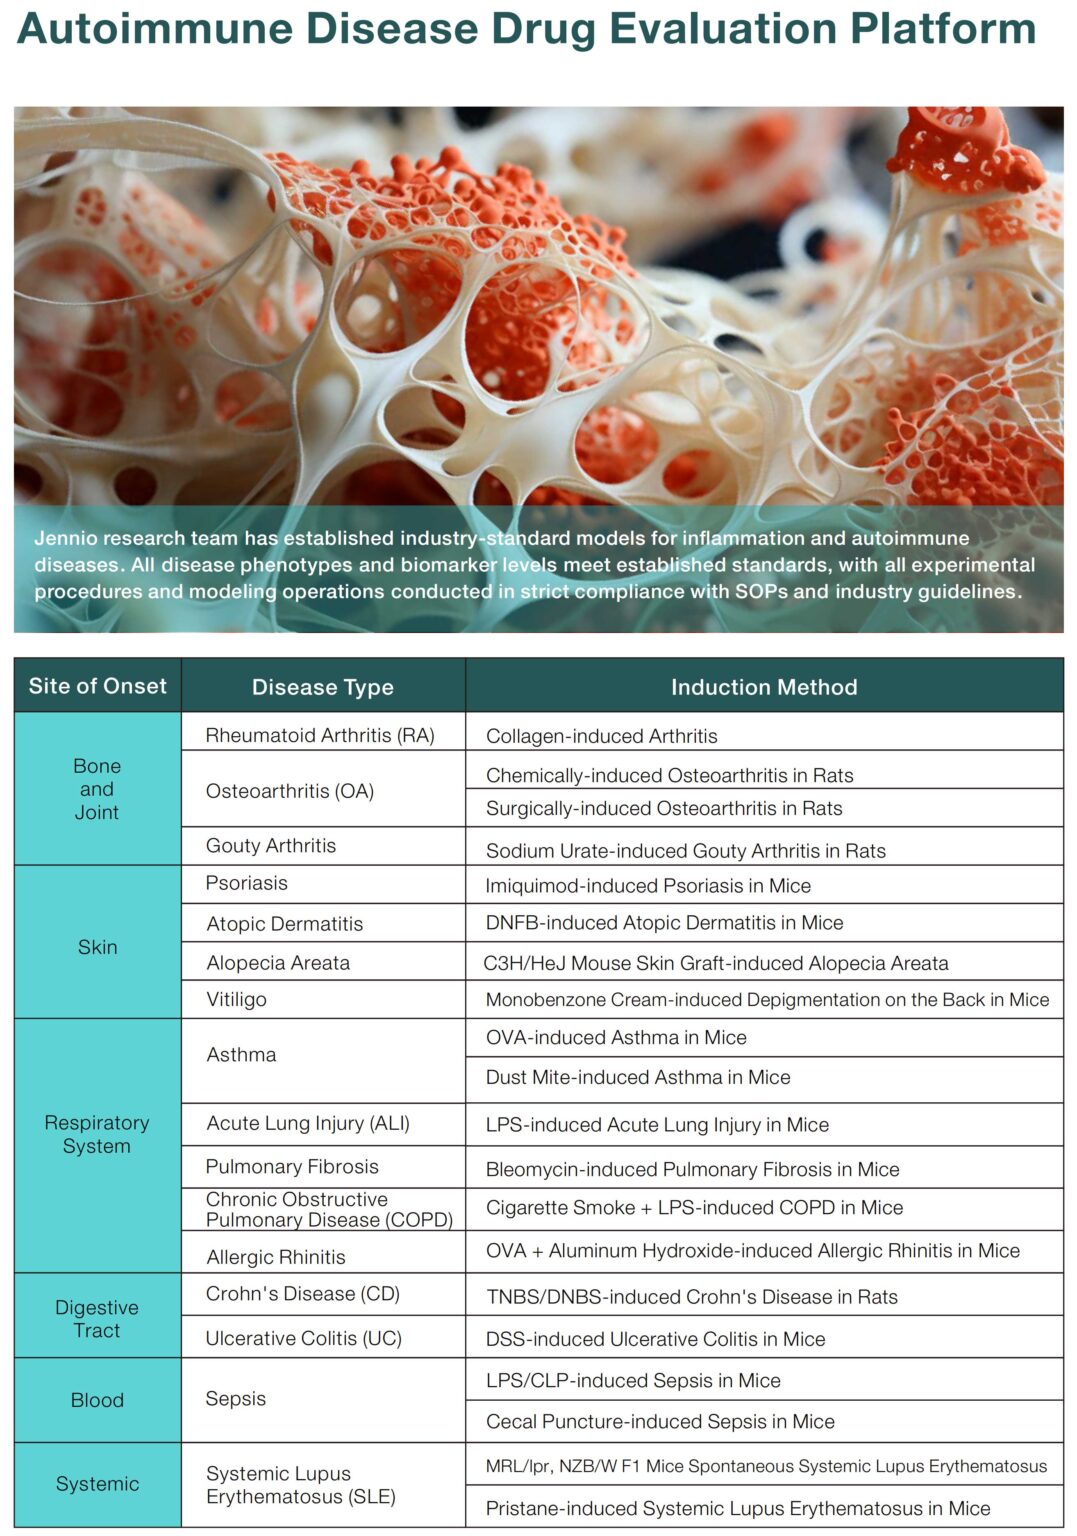
When numbers stop telling the true story, the lab feels the heat — that’s the problem-driven pulse here. Many clinical research teams trip on subtle bias, misaligned controls, or stray batch effects that skew conclusions, especially in studies using autoimmune disease models. Start there: clear expectations for endpoints and standard operating notes cut the noise early and save months of back-and-forth with statisticians.
Where the data usually trips up
Most interpretation errors come from a few repeat offenders. Watch these carefully:
– Inconsistent baselines or control arms that aren’t truly comparable.
– Hidden batch effects from reagents, operator shifts, or equipment drift.
– Overfitting models to small sample sets or noisy readouts.
– Mislabelled metadata (timepoint, strain background, or treatment group).
Operational production teardown — practical steps
Break the experimental pipeline down, step by step. Check sample handling, randomisation logs, and instrument calibration before touching the analysis. In the teardown, call out {main_keyword} and {variation_keyword} where they belong — in your tracking sheet and audit trail — so nobody assumes a variable is fixed when it’s not. Practical notes:
– Confirm strain background and genotyping for knockout model or transgenic mice lines before phenotyping.
– Lock down data formats and timestamps at acquisition to prevent merge errors.
– Preserve raw files and a minimal processed set; re-run one intermediate transform to validate assumptions.
Real-world anchors that prove the point
Look to the reproducibility dialogue: a Nature survey in 2016 reported that over 70% of researchers had failed to reproduce another scientist’s experiments — that’s not guesswork, it’s a caution. Add to that institutional practice: major repositories like Jackson Laboratory and NIH-curated resources highlight the need for documented breeding records and standardized EAE or colitis model protocols. These anchors remind teams that problems are systemic, not personal, and that standardized model documentation prevents wasted effort.
Common mistakes and quick fixes
Fixes should be straightforward and fast. Try these remedies:
– Mistake: pooling different batches without checking batch effect. Fix: include batch as a covariate or re-balance experiment design.
– Mistake: relying only on single endpoint readouts (weight loss, clinical score). Fix: add secondary phenotyping like histology or cytokine profiling to triangulate results.
– Mistake: mislabeled samples. Fix: institute barcode tracking and weekly cross-checks — simple, but it stops a lot of rework.
Small tools matter. A quick pilot run with 6–8 animals per group often reveals whether your assay window and sampling frequency capture the biology you expect — better than a blind large cohort that later proves incoherent.
Advisory — three golden rules for evaluation
1) Metric: Reproducibility index — track how often an internal replicate reproduces primary findings across at least two independent cohorts. Expect ≥80% concordance for robust results.
2) Metric: Metadata completeness — require 100% of samples to have strain background, age, sex, genotype, and handler logged. Missing metadata is a non-starter.
3) Metric: Endpoint triangulation — mandate at least two orthogonal readouts (e.g., clinical score + histology or cytokine panel) for any decisive claim in autoimmune models. This reduces false positives and clarifies mechanism.
These are practical checks you can run weekly — they catch drift early and keep interpretation honest. Jennio Biotech fits here as a partner that supplies consistent model resources and documentation so teams spend less time chasing provenance and more time understanding biology.
Final word: rigorous basics beat clever fixes — stick to them and your data will speak plainly. —